该研究探讨了神经科学中的核心联接假说(linking hypothesis,即将神经群体活动映射为行为表现的定量规则):能否确立单一且定量的神经读出模型,在包含 64 项物体识别测试的广泛任务集上,同时预测人类行为表现的误差模式与绝对水平。作者通过光线追踪渲染生成 5760 张自然变异图像,测量了 104 名人类受试者的识别行为,并利用多电极阵列同步采集猕猴 V4 与下颞叶(IT)皮层的神经群体放电,系统比对了 944 类候选联接假说。结果表明:仅需对分散分布在 IT 皮层的平均放电率进行基于学习的线性加权求和(LaWS of RAD IT),即可高精度预测人类的核心物体识别行为;相比之下,底层像素模型、类 V1 模型、V4 群体表征,以及精细时间编码与高度模块化方案,均未能达到同等的一致性或缺乏额外预测增益。
研究背景
灵长类腹侧视觉通路终端的 IT 皮层普遍被认为支持核心物体识别,脑损伤、群体神经解码以及知觉相关性研究均为此提供了实证支持。然而,“IT 皮层包含物体类别信息”并不等同于“IT 神经活动足以定量解释人类的实际行为表现”。以往多数神经解码研究仅局限于少数孤立任务,测试解码正确率是否高于随机水平,或评估神经放电与知觉判断的相关性;此类分析难以排除其他脑区或复杂编码形式的贡献,也未能阐明下游神经环路应如何读取信息,以在不同难度的任务集上重现人类特有的行为起伏。此外,绝对正确率受神经元采样数量与测量噪声的显著影响,仅凭单一任务的正确率难以甄别预测偏差究竟源于神经表征的不匹配还是采样密度的不足。
为了建立严谨且可证伪的神经—行为联接假说,必须明确指定候选脑区、时间整合窗口、放电特征提取形式及下游解码规则,并在宽广的任务难度梯度上进行定量比对。跨任务的行为表现起伏模式提供了严苛的约束:一个有效的假设不仅要在简单与高难度任务之间重现与人类一致的表现波动趋势(模式一致性),还需在整体识别能力上达到相符的幅度(表现水平),而不能在简单任务上过拟合、在高难度任务上系统性崩溃。跨个体的人—人一致性(human-to-human consistency)构成了数据噪声上限下的基准参照。
本研究利用 5760 张参数化渲染图像构建了 64 项行为测试任务,量化了人类受试者的辨别力指标 d′,并记录了猕猴 V4 与 IT 皮层对相同图像的神经响应,在统一框架下评估了多种候选联接假说。评估涵盖简单的线性加权读出、精细时间片编码、试次间放电相关性以及皮层区域模块化假设。实验表明,IT 皮层平均放电率的简单线性加权求和足以匹配人类的识别行为模式,而中低阶表征与 V4 神经群体则无法实现相符预测。该结论适用于短暂呈递(100 ms)的核心物体识别场景;估算的神经元规模依赖于试次平均向单试次推导的假设,证实了简单加权读出在该任务空间内的充分性。
研究思路
研究设计采用系统性的预测比对策略:令每一个候选联接假说在完全相同的 64 项测试中输出预测辨别力指标(d′),并与人类受试者的实测 d′ 表现模式进行统计对照。技术流程分为四个环节:(1) 构建包含自然几何变异的物体识别行为基准;(2) 对同一批图像刺激采集灵长类视皮层大规模多通道神经元响应;(3) 将文献中的代表性假说参数化为具体的编码—解码计算模型;(4) 通过交叉验证评估模型对人类行为表现的拟合优度。
该范式建立了清晰的证伪逻辑:不同计算假说预测出截然不同的跨任务 d′ 响应模式,从而排除了普遍适用的平庸解。评价指标确立为两个维度:一致性(consistency,即 64 项测试中预测 d′ 与人类实测 d′ 的 Spearman 秩相关系数)与相对表现水平(performance,即预测 d′ 与人类 d′ 比值的中位数)。以人类个体之间的表现相关性(human-to-human consistency)作为统计评估的基准阈值区间。
方法
行为测试方面:从 8 个基础物体类别(basic-level categories:动物、船只、汽车、椅子、面孔、水果、飞机、桌子)中各选取 8 个具体实例,建立包含 64 个三维几何物体的数据库。利用 POV-Ray 光线追踪渲染软件生成二维写实图像,并在渲染过程中系统操纵六个空间几何参数(水平与垂直空间坐标、三维尺寸、围绕三个主轴的旋转偏角)。设计涵盖三个空间几何变异梯度(低、中、高),共生成 5760 张 256×256 像素的灰度测试图像(中/高变异条件下,水平位移为 ±1.2°/±2.4°,垂直位移为 ±2.4°/±4.8°,三轴旋转为 ±45°/±90°,尺度缩放比例分别为 ×[1/1.3, 1.3] 与 ×[1/1.6, 1.6]),图像背景选用非重复的自然纹理。招募 104 名人类受试者(通过 Amazon Mechanical Turk 平台完成,其实验室复核相关系数达 0.94)执行 8 选 1 强制选择辨别任务:中央注视点呈递 500 ms → 中央 8° 视角测试图像呈递 100 ms → 300 ms 灰屏延迟 → 呈现 8 张候选类别示意图供按键选择,测试全程无反馈。基于合并混淆矩阵依据信号检测论计算二分类辨别力指标 d′(d′ = Z(TPR) − Z(FPR));3 个任务集 × 8 个目标类别 × 3 个变异等级理论上对应 72 项测试,排除高变异条件下处于随机水平的面孔辨别后,最终确定 64 项标准评估测试。
神经生理记录方面:选用两只雄性恒河猴(体重 7 与 9 kg),在左大脑半球各植入三个 10×10 规格的 Blackrock 微电极阵列(1 个位于 V4 区,2 个位于 IT 皮层),共获得 296 个视觉反应性记录位点(IT 皮层 168 个位点:后部 PIT 76 个、中部 CIT 75 个、前部 AIT 17 个;V4 区 128 个位点)。每张图像以快速连续视觉呈递(RSVP)方式呈递至少 28 次(中位数约 50 次;100 ms 图像刺激 + 100 ms 灰屏间隔),两只动物分别记录 68 与 65 个实验日;分析主要基于多单位活动(MUA)。神经反应强度量化为刺激呈递后 70–170 ms 窗口内的放电计数减去刺激前基线放电,并除以该位点当日放电的标准差。下游解码器采用生物学可行的线性读出机制:支持向量机(SVM,采用 L2 正则化)与相关解码器(CC,基于类别均值向量的相关性分类),采用“一对其余”(one-vs-rest)架构训练 8 个二分类器,以最大决策裕度作为行为判决输出,执行至少 50 次独立的交叉验证拆分。对照特征包括原始图像像素、类 V1 的 Gabor 滤波器组、PHOG、SIFT、HMAX-SLF 及 L3 等经典计算机视觉特征模型。评估标准以人类个体间一致性(中位数 0.929,68% 置信区间 [0.882, 0.957])作为基准参考带,相对表现水平需接近 1.0。
主要结果
-
人类核心物体识别能力的量化基准(图 3):64 项测试任务的辨别力 d′ 呈现出广泛的难度分布——基础类别分类的平均 d′ 达到 3.46,车辆亚类细分任务平均 d′ 为 1.49,而高变异条件下的面孔个体辨别平均 d′ 仅为 0.50;随着几何图像变异等级提升,平均 d′ 从低变异的 2.39 依次下降至中变异的 1.89 与高变异的 1.50。这表明人类视觉识别在面对视角与位置变异时并非严格绝对恒常,其容忍能力与物体间的形状相似度存在交互效应。人类个体与群体合并模式之间的 Spearman 相关系数中位数为 0.93,表明该行为模式在群体中高度一致。
-
基于 IT 平均放电率的线性加权求和准确匹配人类表现(图 4、5、7):基于 128 个 IT 记录位点、70–170 ms 响应窗口平均放电率并结合 SVM 解码的 LaWS of RAD IT 假说,其在 64 项任务中的预测 d′ 模式在统计学上与人类行为表现无法区分,模型一致性落入人类个体间一致性的基准参考区间;当记录位点数量增加至约 100 个时,模式一致性即趋向饱和平台。
-
中低阶计算特征及所有基于 V4 的假说均无法匹配人类表现(图 5、6、7):原始像素、类 V1 滤波器、PHOG、SIFT、SLF、L3 以及基于 V4 神经群体的所有候选假说,其模式一致性均显著低于人类表现基准带,且增加特征维度或更换分类算法均无法弥合这一差距。V4 群体的预测偏差呈现系统性模式错位:其在部分低变异任务中的预测表现高于人类实际水平,而在高变异复杂任务中则显著低于人类表现。将刺激限制在中央凹或对侧视野范围内后,V4 的模式一致性仍仅为 0.196(同期 IT 为 0.868),排除了感受野空间分布不均导致的解释。
-
精细时序编码与特化模块化假设未显示额外预测增益(图 5c–e):显式保留多电极同步记录的试次间相关结构(simultaneous)与打乱试次相关(shuffled)的解码表现无统计差异;将 100 ms 整合窗口细分为 10 个 10 ms 连续时间片的精细时间序列编码,预测一致性未见提升;实施强模块化读取(例如面孔辨别仅读取面孔反应特化位点)亦未提高一致性,且在部分任务中表现出轻微下降趋势。在面孔检测(二分类)任务中,最优权重前 5% 的神经位点中 87.5% 属于面孔选择性位点,而在面孔辨识(个体细分)任务中该比例仅为 12.5%。
-
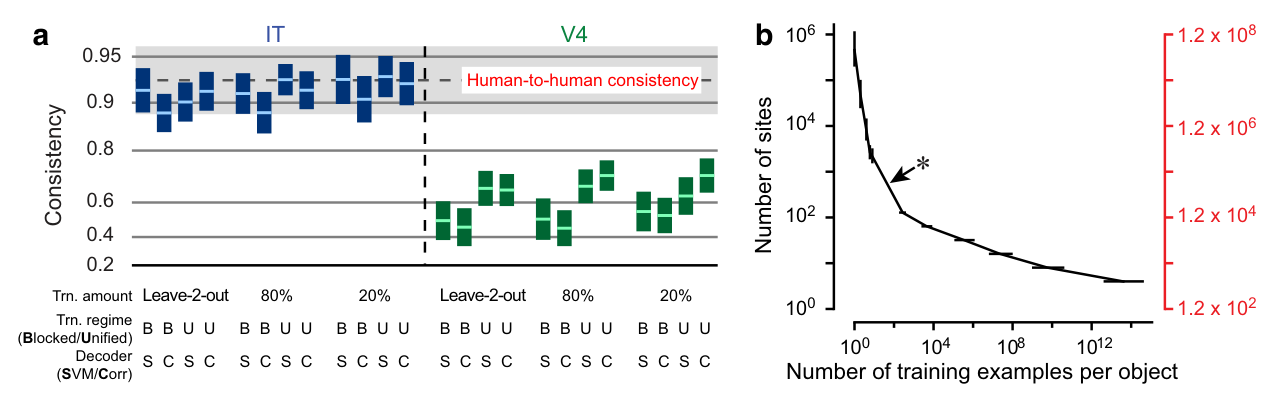
支持全量行为所需的神经元数量估算(图 7b、8、10):回归拟合显示,约 529 个试次平均的 IT 记录位点(V4 区估算需约 22,096 个)可在绝对表现水平上匹配人类表现;单神经元隔离分析(SUA)显示单单位的效率需求约为多单位(MUA)的 2 倍,单试次随机波动读出所需的神经元数量约为试次平均数据的 60 倍;据此推算,约 60,000 个分布式的 IT 单神经元即可同时在模式一致性与绝对表现幅度上重现人类核心识别能力,且单个新物体仅需约 40 张训练样本图像(68% 置信区间 [30, 60])即可完成线性分类边界的学习。时间窗口分析表明,读出一致性在刺激呈递后 100 ms 左右进入平台期,并稳定维持约 100 ms(图 7c, d)。
图注解读
图 1 · 任务设计与四种可能结局
原文图注:Figure 1. a, Object recognition tasks. To explore a natural distribution of shape similarity, we started with eight basic-level object categories and picked eight exemplars per category resulting in a database of 64 3D object models. To explore identity preserving image variation, we used ray-tracing algorithms to render 2D images of the 3D models while varying position, size, and pose concomitantly. In each image, six parameters (horizontal and vertical position, size, rotation around the three cardinal axes) were randomly picked from predetermined ranges (see Materials and Methods).Theobjectwasthenaddedtoarandomlychosenbackground.Alltestimageswereachromatic.Humanobserversperformedalltasksusingan8-wayapproach(i.e.,seeoneimage,chooseamongeight;seeMaterialsandMethods).Twokindsofobjectrecog... b, Possible outcomes for each tested linking hypothesis. We defined multiple candidate neuronal and computational linking hypotheses (Fig. 5), determined the predicted (i.e., cross-validated) object recognition accuracy (d') of each linking hypothesis on the same 64 tests (y-axis in each scatter plot), and compared those results with the measured human d' (x-axis in each scatter plot). A priori,eachtestedlinkinghypothesiscouldproduceatleastfourpossibletypesofoutcomes.Thepatternofpredicted d' might be unrelated to or strongly related to human d' (left vs right scatter plots). We quantified that by computing consistency, the correlation between predicted d' and actual human d' across all 64 object recognition tests. Average predicted d' might be low or matched to human d' (bottom vs top scatter plots). We quantified performance by computing the median ratio of predicted d' and actual human d', across all 64 object recognition tests...
图 a 概括了实验任务体系:涵盖 64 个三维物体模型、参数化几何光线追踪渲染以及 8 选 1 强制选择任务架构,每个测试组包含 8 个二分类判别,共形成 64 项独立的 d′ 评估指标;图 b 构建了评估假设有效性的二维空间矩阵——横轴为人类实测表现,纵轴为模型预测表现,模型预测与人类表现可能呈正相关或无关(一致性高/低),平均表现幅度可能匹配或不足(表现水平高/低),唯有兼具高一致性与对齐幅度的模型才能确立为充分的神经联接假说。该图奠定了本研究的定量证伪评估标准。
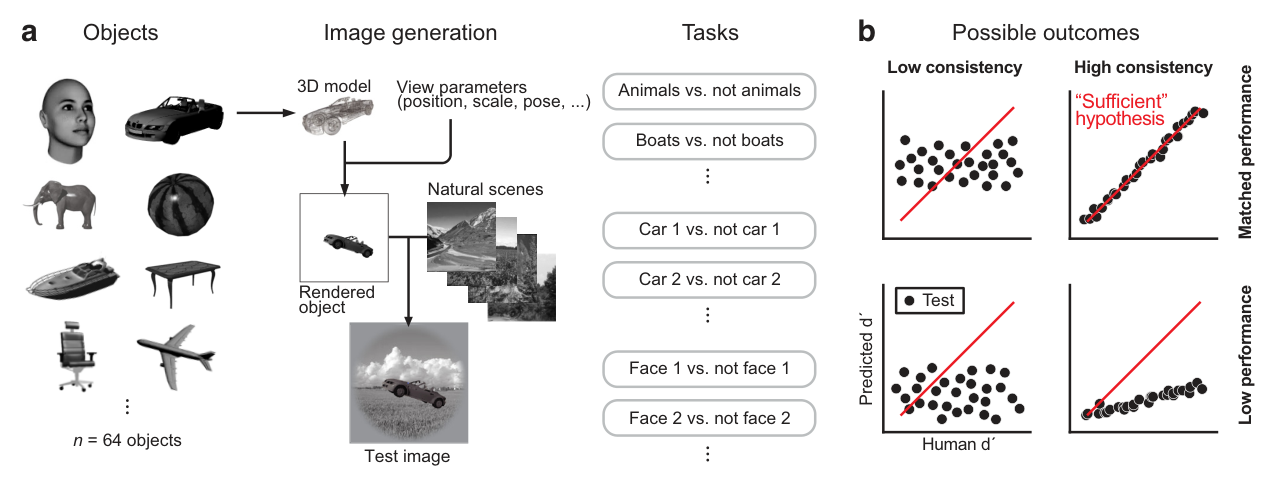
图 2 · 神经记录布局与响应矩阵
原文图注:Figure 2. a, We used multielectrode arrays to record neural activity from two stages of the ventral visual stream [V4 and IT (PIT, CIT, AIT)] of alert rhesus macaque monkeys. We recorded neural responses to the same images used in our human psychophysical testing. Each image was presented multiple times (typically ~50 repeats, minimum 28) using standard rapid visual stimulus presentation (RSVP). Each stimulus was presented for 100 ms (black horizontal bar) with 100 ms of neutral gray background interleaved between images. Although some of our neural sites represented single neurons, the majority of our responses were multiunit (see Fig. 8a). The rasters for repeated image presentations were then tallied within a defined time window (e.g., 70–170 ms after image onset, red rectangle, black vertical line indica... b, Approximate placement of the arrays in V4 (green shaded areas) and IT (blue shaded area) is illustrated by the black squares on two line drawings representing the brains of our two subjects.
面板 a 说明了神经信号的提取与预处理流程:展示了快速连续视觉呈递(RSVP)范式、刺激曝光与灰屏时序、在 70–170 ms 响应窗内积分得到放电率向量的过程,以及 5760 张图像诱发的群体响应矩阵组织结构;面板 b 标注了微电极阵列在两只猕猴大脑 V4 与 IT 皮层的植入解剖解剖位点。该图界定了后续所有计算解码分析的原始神经生理输入数据结构。
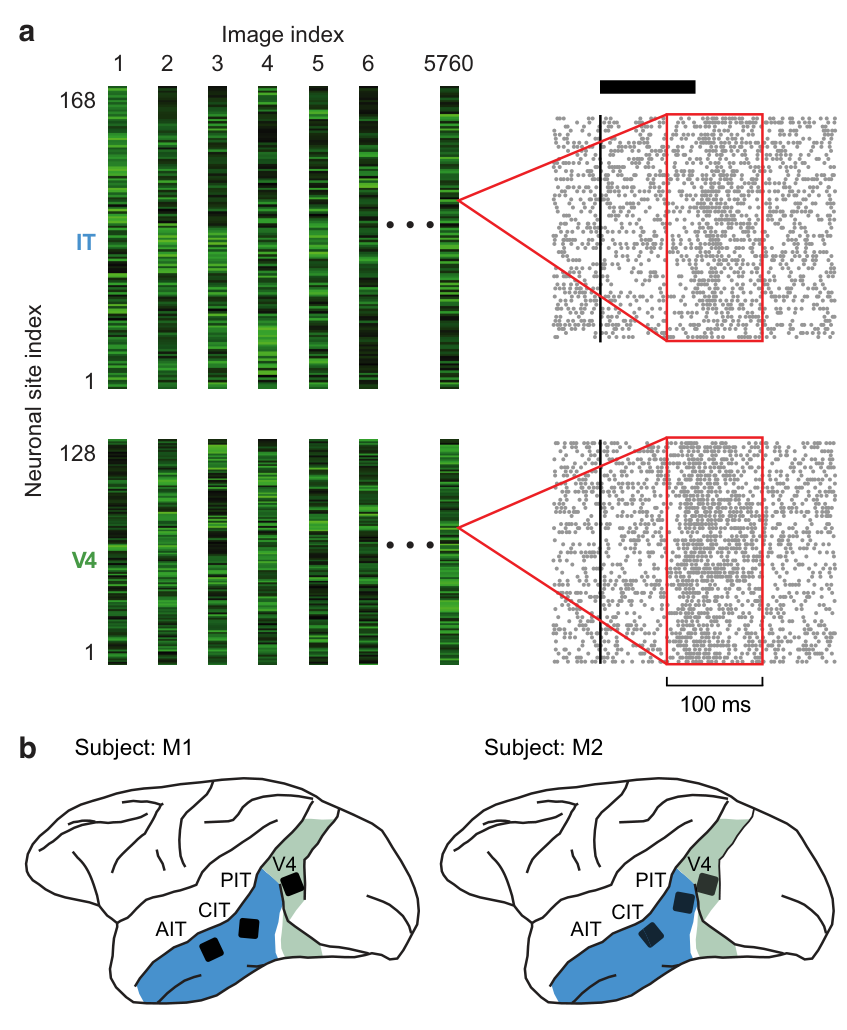
图 3 · 人类 64 项测试的成绩全景
原文图注:Figure 3. a, Each color matrix from left to right summarizes the pooled human d' for each of the three task sets ranging from basic level categorization to subordinate level face identification. In each matrix, the amount of identity preserving image variation was increased from low (bottom) to high (top), resulting in a total of 64 behavioral tests. Red represents high performance (d'=5) and blue low performance (d'=0). For each 8-way test set and each level of variation, the computed eight d's were based on the average confusion matrix of multiple observers (basic level categorization, n=29, car identification, n=39, face identification, n=40; see Materials and Methods for more information). b, Human to human consistency. The scattergram shows the performance (d') of one human observer plotted against the performance (d') of the pooled population of human obser...
面板 a 展示了人类核心识别行为基准:包含三个任务集(基础分类、汽车辨识、面孔辨识)分别在三个变异等级下的 d′ 色彩响应矩阵,难度自下而上递增;面板 b 以散点图对比了个体受试者与群体合并数据的对应关系(示例 Spearman 相关系数为 0.941,中位数 0.929),该虚线与围绕的置信带构成了后续评估各神经联接假说的一致性判定区间。
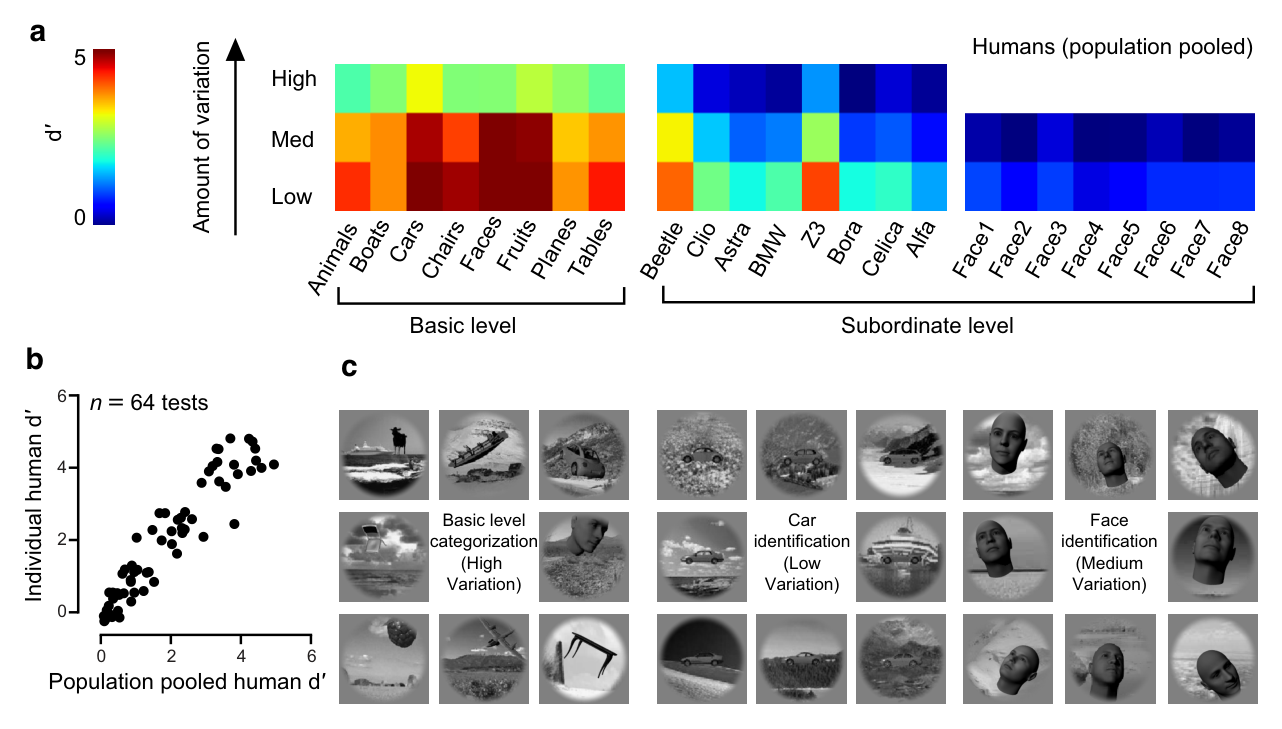
图 4 · 一个胜出假设的完整预测
原文图注:Figure 4. Predicted performance pattern of an example LaWS of RAD IT neuronal linking hypothesis. In this example, the hypothesized neural activity that underlies behavior is as follows: in IT, from 128 units, mean firing rate, in a time window of 70–170 ms; and the decoder is an SVM decoder. a, Based on the aforementioned features of neural activity, a depiction of the outputs of two example decoders for two tasks from two different task sets. For each task set (basic categorization, subordinate identification) and each variation level (low, medium, high), we randomly divided our image responses into "training" and "testing" samples. We used the "training" samples, depicted by the green response vectors, to optimize eight "one-vs-rest" linear decoders. The performance of each decoder was then evaluated on the "testing"... b, Predicted pattern of behavioral performance for all 64 behavioral tests... c, To facilitate comparison among different linking hypotheses and with human behavior (see Fig. 5), we strung out the color matrices into a color vector grouping task sets at each variation level.
面板 a 以具体分类任务说明了训练—测试集拆分与线性分类器判决裕度的分布特性;面板 b 给出了该假说在全部 64 项测试上的预测 d′ 矩阵,其跨任务起伏模式与图 3a 所示的人类实测数据高度对应;面板 c 将二维色彩矩阵展开为一维向量,用于在图 5 中与不同假说进行横向排列比对。该图直观展示了 IT 神经群体平均放电率的线性读出能够复现人类行为特征。
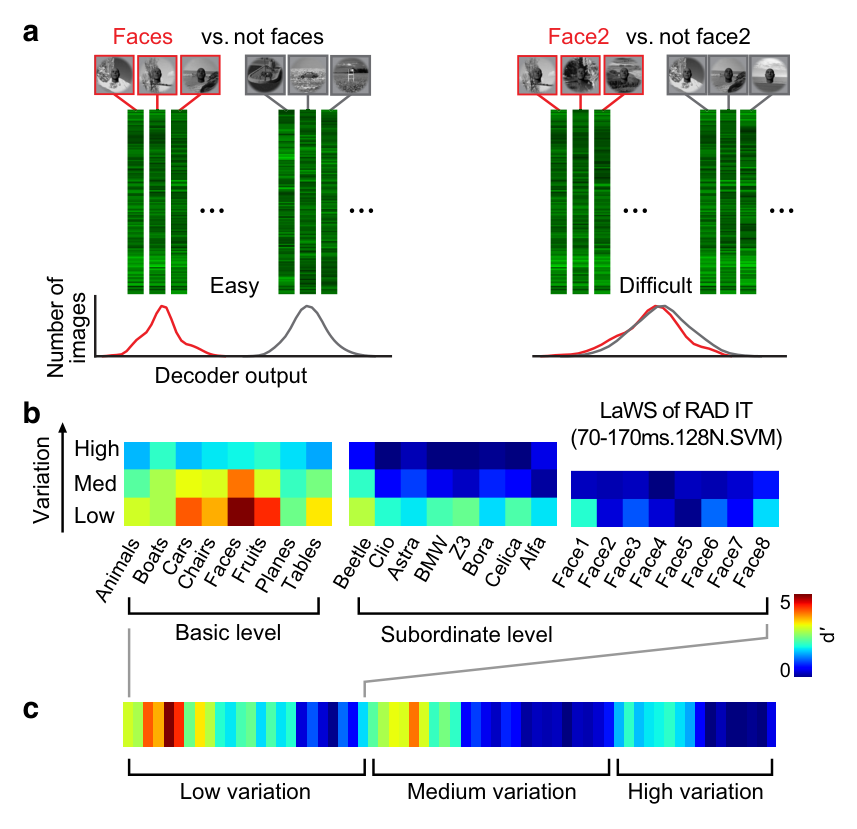
图 5 · 候选联接假设的横向对照
原文图注:Figure 5. a, Candidate linking hypotheses that we explored were drawn from a space defined by four key parameters: spatial location of sampled neural activity, the temporal window over which the response of our units was computed (mean rate in this window), the number of units, and the type of hypothesized downstream decoder. Each candidate linking hypothesis is a specific combination of these parameters. For example, in green is a V4-based linking hypothesis with a temporal window of 70–170 ms that includes 128 neural sites and uses an SVM decoder. The predicted performance of each linking hypothesis for each behavioral test is depicted as a color vector where blue signifies low predicted performance (d'=0) and red signifies high predicted performance (d'=5). The goodness of each linking hypothesis can be visually evaluated by comparing its color pattern with that of the hu... b, Consistency. To quantify the ability of each linking hypothesis to predict the pattern of human performance (i.e., the similarity between color vectors in a), we computed the Spearman rank correlation coefficient between predicted performance and actual (pooled human, 104 subjects) across all task d's. Median human-to-human correlation is indicated by the dashed line (median Spearman correlation coefficient of 0.929). The gray region signifies the range of human-to-human consistency (68% CI=[0.882,0.957]). Each bar represents a different candidate linking hypothesis... Within the context of IT-based linking hypothesis, we explored finer grain temporal codes (c). We also took advantage of our simultaneous multielectrode array recording to assess the impact of trial-by-trial firing rate correlation on the pattern of performance predicted by our most successful linking hypothesis (d). We considered the idea of a modular IT linking hypothesis with different subregions of IT being devoted exclusively to certain kinds of tasks (e).
面板 a 汇总了四参数搜索空间(脑区来源、响应时窗、单元数量、解码器类别)中各候选假说的预测向量色带;面板 b 比较了各假说的 Spearman 秩相关系数柱状图,灰色参考带指示人类个体间的一致性区间——IT 假说稳定落入人类基准带内,而 V4 及各类计算模型均显著低于阈值;面板 c–e 分别展示了精细时序切片、试次间放电相关性以及皮层特化模块假设的测试结果,显示此类更复杂的机制并未带来额外的预测增益。
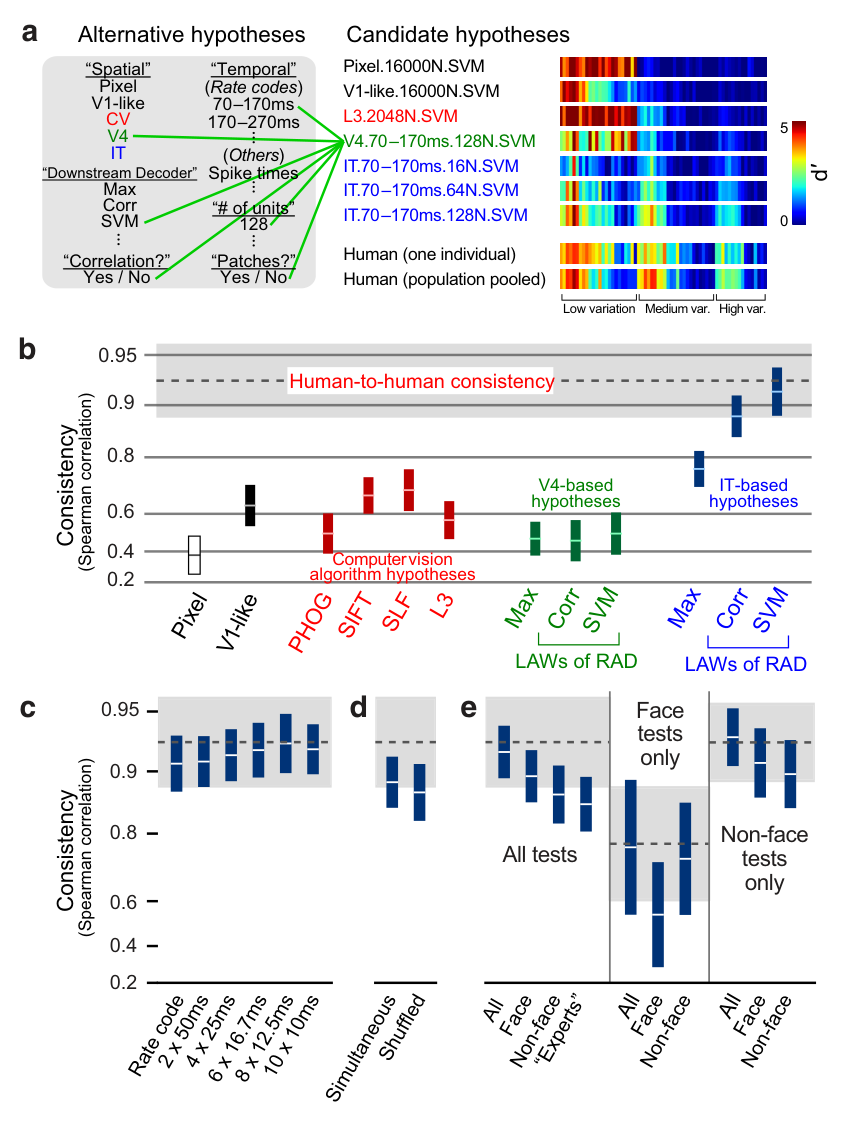
图 6 · 755 个实例化假设的总体散点
原文图注:Figure 6. Exploring a large set of linking hypotheses. The y-axis shows consistency (defined in Fig. 5b) and the x-axis shows performance—the median of the ratio between predicted and actual (human) d' across all 64 tests. In total, we tested 944 types of linking hypotheses, varying the number of neurons/features in each case, for a grand total of 50,685 instantiations considered. Here, we show the results of 755 of those hypotheses. The result of each specific instantiation is shown as a point in the plot with color used to indicate the "spatial" location of the features (IT, V4, V1, or computer vision). We show these examples to illustrate the parameters that we varied, which included spatial location, temporal window, number of units, type of decoder, and a variety of training procedures and train/test splits (see Fig. 10a). The horizontal dashed line indicates the average human-to-human consistency and the horizontal gray band represents variability in human-to-human consistency... Any linking hypothesis that falls in the red dashed circle is perfectly predicting human performance on these 64 tests.
横轴表示相对表现水平(比值为 1.0 代表与人类表现幅度相等),纵轴表示跨任务模式一致性,红色虚线区域标注了“表现模式与绝对幅度双重吻合”的目标空间。结果显示,基于 IT 皮层的神经群体(蓝色散点)是唯一定向聚集于该目标区域的假说集合;V4 群体(绿色散点)、类 V1 模型(黑色散点)及计算机视觉模型(红色散点)在模式一致性上均系统性落后。IT 数据集内部的纵向发散主要受采样记录位点规模的调制(见图 7b)。该全景分布直观印证了主结果第 2 条与第 3 条结论。
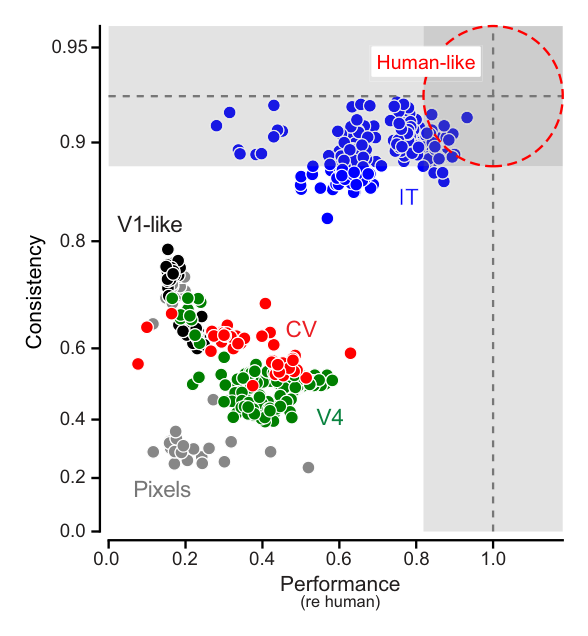
图 7 · 位点数与时间窗的定量效应
原文图注:Figure 7. Effect of number of units and temporal window on consistency and performance. Here, we show the results for the LaWS of RAD linking hypotheses (see text), but results are qualitatively similar for other hypotheses. a, Scattergrams show predicted performance (d') for two neuronal linking hypotheses, IT (blue) and V4 (green), plotted against the actual human performance on all 64 tests: low variation (open circles), medium and high variation (filled circles). The number of units increases from 16 neural sites (left) to 128 neural sites (right). For each linking hypothesis, we also computed its performance: the median of the ratio between predicted and actual human performance across all d' for all 64 tests. b, Performance versus consistency for the V4- and IT-based linking hypotheses as a function of the number of (trial-averaged) units. The curve fits are [IT, r2=0.996; V4, r2=0.91] and they predict that ~529 IT trial-averaged neural sites and ~22,096 V4 trial-averaged neural sites would match human performance under the LaWS of RAD linking hypothesis. c, Consistency for different temporal windows of reading the neural activity. Each point is computed with a 100-ms-wide window and the x-axis shows the center of that window. The number of trial-averaged neural sites was fixed at 128. d, Consistency versus performance for the LaWS of RAD IT linking hypothesis at several progressive temporal windows with the center location starting at the time of image onset (0 ms) and up to 500 ms after image onset. The width of the temporal window was fixed at 100 ms...
面板 a 展示了 IT 与 V4 预测值随单元数量增加的变化散点图,直观反映了 V4 在复杂几何变异任务中预测力欠拟合、在简单任务中过拟合的结构性偏差;面板 b 给出了单元数量对表现指标的非线性回归曲线,模型预测达到人类表现水平需约 529 个 IT 试次平均记录位点,而 V4 区推算需约 22,096 个;面板 c 与 d 扫描了不同时间整合窗口的预测效能,表明一致性在刺激呈递后 100 ms 处迅速上升并形成宽阔的平台期。
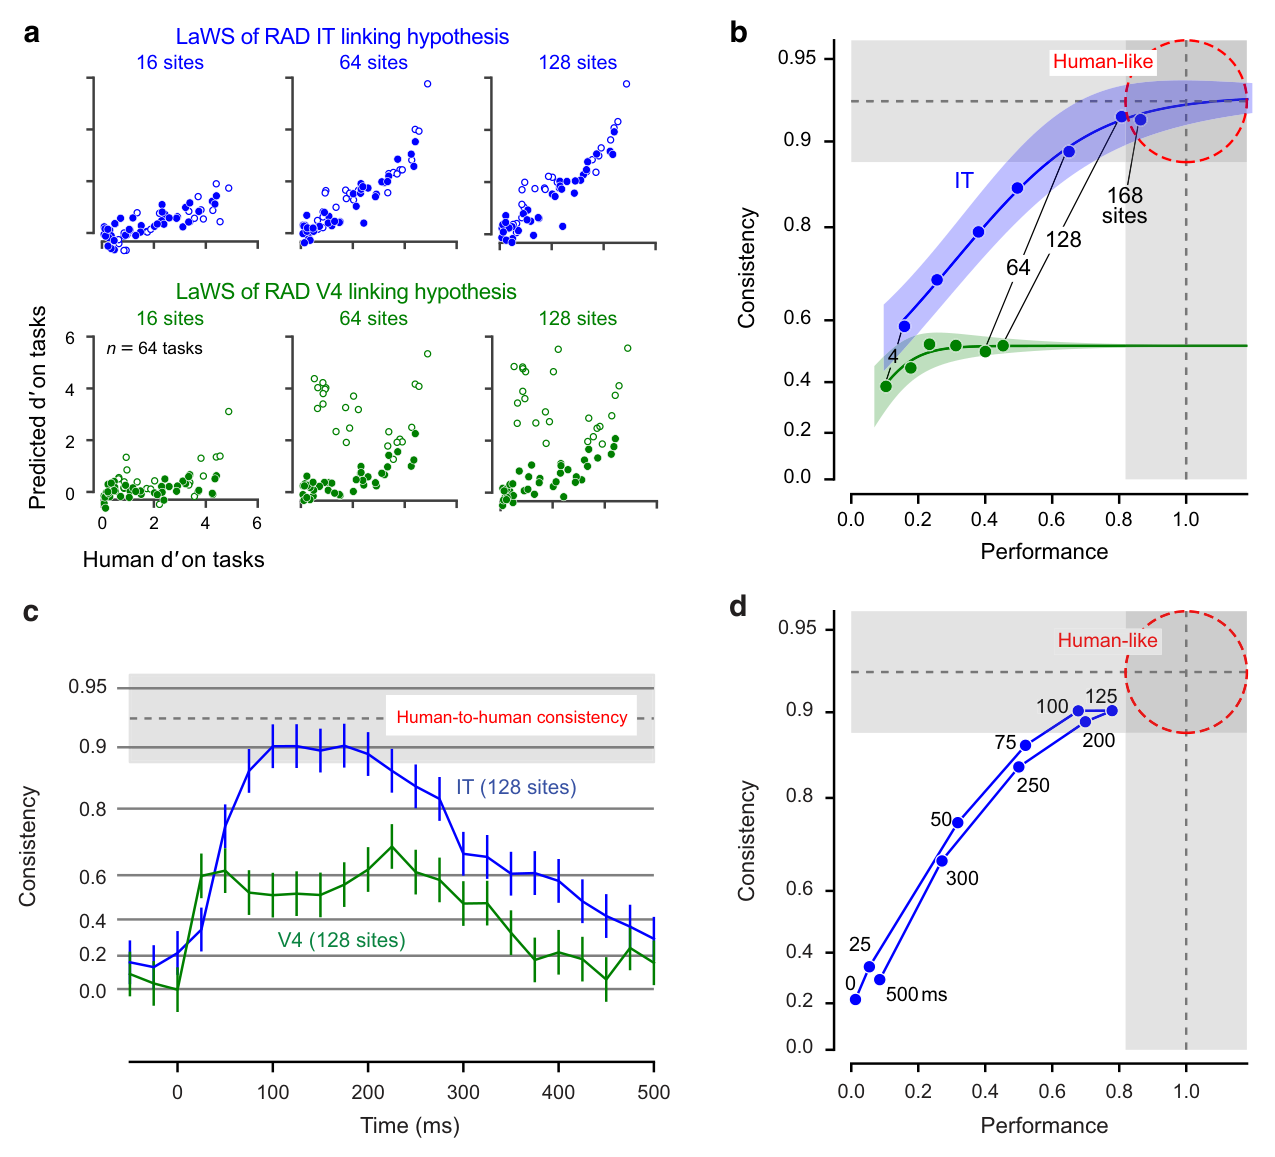
图 8 · 从多单位到单单位、从平均到单试次
原文图注:Figure 8. a, SUA versus MUA linking hypotheses. We used a profile-based spike sorting procedure (Quiroga et al., 2004) and an affinity propagation clustering algorithm (Frey and Dueck, 2007) to isolate the responses of 16 single units from our sample of 168 IT neural sites. The minimum signal-to-noise ratio (SNR) for each single unit cluster was set to 3.5, with SNR defined as the amplitude of the mean spike profile divided by root mean square error (RMSE) across time points. Consistency with the human pattern of performance versus performance for SUA (red) and MUA (black). We estimate that twice as many neurons are needed so that the consistency-performance relationship of our SUA linking hypothesis matches that of our MUA linking hypothesis... b, Single trial versus averaged trials linking hypotheses. Because human subjects were asked to make judgements on single image presentations, we also explored a "single trial" training and testing analysis in which we treated the responses of the neural units to each images presentation as a new and independent set of neural units (i.e., "unrolled" the trial dimension into the unit dimension). Consistency versus performance for the single-trial (red) and the averaged-trial (black) LaWS of RAD linking hypotheses (based on a correlation decoder). We estimate that ~60 times as many neurons are needed so that the consistency-performance relationship of our single-trial hypothesis matches that of our averaged-trials hypothesis.
面板 a 对比了单神经元分离信号(SUA)与多单位信号(MUA)的一致性—表现轨迹,推算达到相同效能单单位数量约为多单位的 2 倍;面板 b 对比了单试次读出分析与多试次平均读出,估算单试次读出需增加约 60 倍的神经元群体规模。这两组换算因子是将 529 个多试次平均位点外推为约 60,000 个单神经元生物学群体的换算基准。
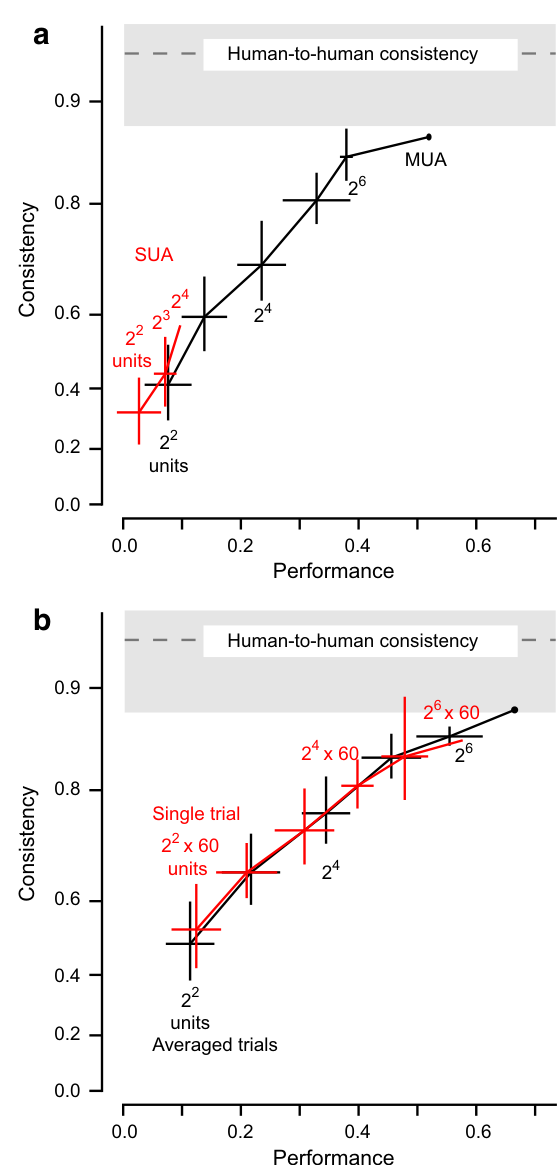
图 9 · IT 三个亚区无本质差别
原文图注:Figure 9. No significant difference in consistency and performance of IT subpopulations was seen when parsed based on anatomical subdivision: PIT versus CIT versus AIT. Based on anatomical landmarks, we could conservatively divide our population of 168 IT neural sites into the following: 76 in PIT, 75 in CIT, and 17 in AIT. a, Comparison of the consistency values for IT populations when neural sites respected anatomical boundaries (PIT vs CIT vs AIT) in contrast to a "control" populations in which the sites were randomly picked from all three anatomical subdivisions. There was no significant difference between the IT populations regardless of whether we restricted our population to 17 neural sites (limiting our analysis to the number of neural sites in AIT our least sampled anatomical subdivision) or expanded to 75 neural sites and compared PIT and CIT. Similarly, performance (b) showed no significant differences between the different IT populations... Consistency and performance were computed based on our typical 70–170 temporal window using an SVM decoder.
将 IT 神经元样本按解剖分界划分为后部(PIT)、中部(CIT)与前部(AIT)独立训练解码器,其一致性(a)与相对表现(b)与随机混合采样的对照群体无统计学差异;在固定亚区单元数量的前提下,各亚区表现高度一致,表明该线性可分性广泛分布在整个下颞叶皮层,排除了预测效应完全由前部 AIT 少数特化区域所驱动的假设。
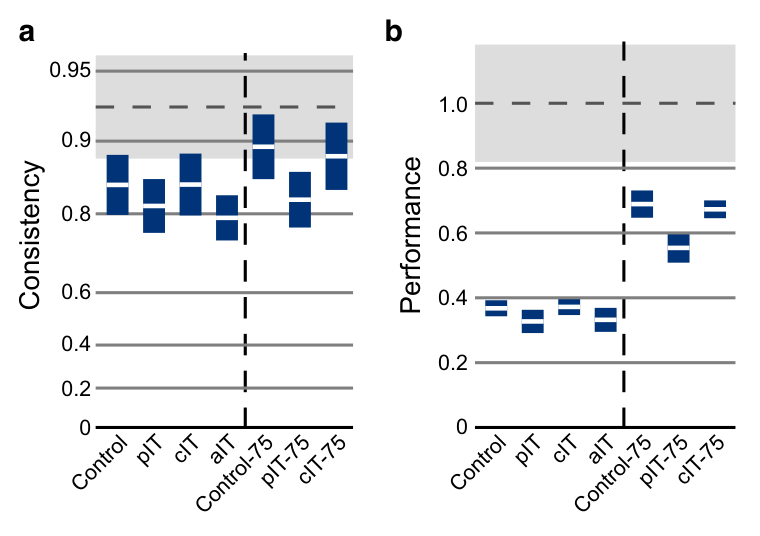
图 10 · 训练协议与"数据换神经元"的权衡
原文图注:Figure 10. a, Effect of the training procedure. Shown are consistency values for LaWS of RAD V4 and IT linking hypotheses under different training procedures. The number of units was fixed to 128 units and the temporal window was 70–170 ms after the onset of the image presentation. Two types of decoders were tested (SVMs and CCs). We also varied the number of images used to train the decoder (leave-2-out: for each class, all images but two were used as the training set and the remaining two were used for testing; 80%: 80% of images were used for training, and the held-out 20% were used for testing; 20%: similar to 80%, but 20% were used for training and 80% for testing). In the blocked training regime, the training and testing of a decoder was done for each variation level separately. For the unified training regime, the decoders were trained across all variations and tested on each variation level separately. b, Trade-off between the sufficient number of units and the number of training images per object for the LaWS of RAD IT linking hypothesis...
面板 a 展示了在不同训练样本规模(留二交叉验证、80% 训练集、20% 训练集)、变异分组策略(分块训练 vs. 统一混合训练)及分类器类型下,IT 假说的一致性保持稳定;面板 b 呈现了解码器所需神经元数量与每类所需训练样本量之间的权衡关系,表明即便利于训练的样本规模缩减至 20%,分布式群体依然能够保持高精度的行为预测,证实解码结果并非来自对样本的过度拟合。
讨论
本研究建立了一个系统化的定量证伪框架:通过构建覆盖多维识别难度的宽广测试空间,检验各类候选编码—解码假说的行为预测能力。实验表明,基于分布式 IT 皮层平均放电率的学习加权和(LaWS of RAD IT)成功重现了人类的核心识别模式,且无需引入试次间噪声相关、毫秒级时序切片或强区域模块化假定。作者强调,这一结果并非否定精细神经编码在其他认知或精细辨别任务中的潜在功能,而是证明对于常规的快速核心物体识别,简单的线性读出已具备充足的定量解释力。
研究在跨物种比较层面提供了证据:猕猴 IT 皮层的神经放电模式能够高精度预测人类受试者的识别行为难度分布,提示灵长类视觉系统共享一种不依赖高级语言语义的底层视觉形状表征,该表征构成了核心物体辨识的基础瓶颈。研究局限在于:约 60,000 个神经元的规模估算依赖于多单位向单试次单单位外推的理论模型;当前的分析基于任务水平的平均 d′,尚未延伸至逐张图像的具体混淆错误预测;此外,研究侧重于揭示 IT 表征对于行为的充分性,关于该表征在上游视皮层中的逐级构建机制,仍需结合分层前馈深度神经网络模型展开进一步探索。
一句话总结
本研究通过大规模跨任务的定量行为对表,证实灵长类下颞叶皮层在 100 毫秒时间窗内的平均放电率结合简单的线性加权读出,足以精准预测人类核心物体识别的全部行为表现起伏。